Observability Engineering Services Outsourcing from Argentina
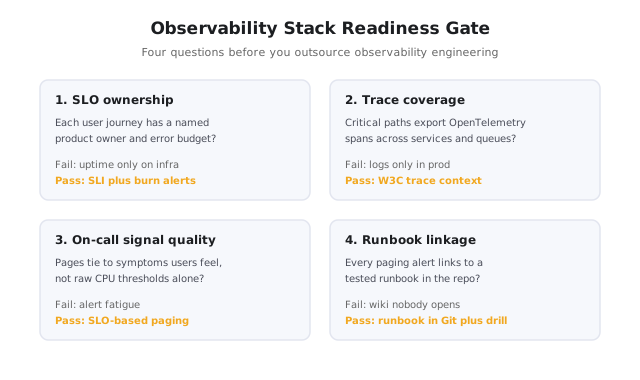
What: Production observability engineering services make incidents debuggable: OpenTelemetry traces across services, SLOs with error budgets, metrics and logs that share trace IDs, paging tied to user-visible symptoms, and runbooks in Git linked from every alert. Who: VP Engineering, heads of platform, and SRE leads at B2B SaaS, fintech, and marketplaces where MTTR is measured in hours because on-call only has grep and CPU graphs. Problem: Dashboards exist but nobody trusts them, alerts wake people without runbooks, checkout or API latency breaks without a span showing where time went, and leadership asks for SLOs that engineering cannot defend. Why nearshore: Observability delivery needs same-day pairing when a burn-rate alert fires before a release, trace propagation breaks in staging, or on-call needs a vendor engineer on the bridge during a game day. How to evaluate us: Ask whether a vendor can pass the Observability Stack Readiness Gate in the hero diagram: SLO ownership, trace coverage, on-call signal quality, and runbook linkage.
We outsource discovery through handoff: instrumentation audits, OpenTelemetry collector IaC, SLI and SLO definitions with burn-rate alerts, dashboard and alert tuning, on-call drills, and handoff documentation aligned with OpenTelemetry documentation, the Google SRE Book on service level objectives, and Grafana alerting documentation. CI/CD pipelines and deploy reliability belong under DevOps engineering; golden paths and developer portals under platform engineering; LLM agent traces only under AI agent observability development. Need one senior SRE embedded in your squad? See hire SRE engineers for staff augmentation.
Siblings Software is a software outsourcing company headquartered in Cordoba, Argentina, with daily overlap on US Eastern time. We have shipped outsourced engineering since 2014 across B2B SaaS, fintech, and enterprise platforms. Browse the full catalog on our all services directory or compare our nearshore development model if procurement is weighing regions. Golden paths and developer portals stay under platform engineering.
What the Service Covers
Observability engineering services outsourcing is the work of making production behavior legible to the people who page: traces that cross services and queues, metrics tied to SLIs, logs correlated by trace ID, and alerts that fire on error budget burn rather than raw CPU. A typical program runs the Observability Stack Readiness Gate, rolls out OpenTelemetry in application and platform repos, defines SLOs product owners sign, tunes paging routes, links runbooks in Git, and rehearses incidents before handoff.
That is different from DevOps engineering, which optimizes pipeline speed, IaC modules, and cluster operations rather than SLI design and trace propagation. It is also different from AI agent observability development, which focuses on LLM spans, eval regressions, and agent tool latency. Observability engineering optimizes for MTTR, defensible SLOs, and on-call signal quality. We pair with platform engineering when collectors belong in golden paths and with QA automation services when synthetic checks feed SLIs.
Quality gates follow what SRE teams expect: no new paging alert without a linked runbook, no SLO change without a product owner signature, and a staging game day before production alert routes change. Teams often combine observability with project-based outsourcing for a first instrumentation wave, then an dedicated development team retainer for ongoing SLO tuning.
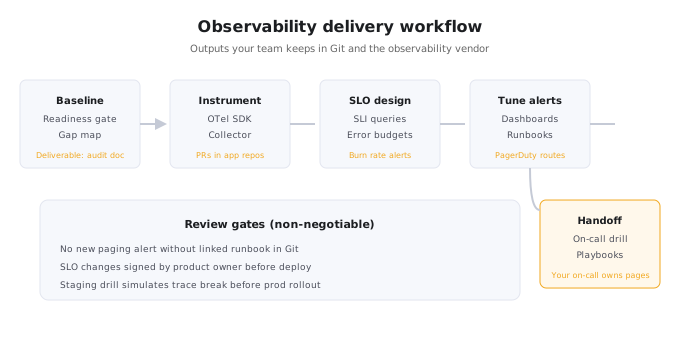
Most production observability programs treat runbook linkage and product-signed SLOs as non-negotiable: on-call should not guess which dashboard to open when error budget burn pages at 2 a.m.
Who It Is For
Platform and product leaders where incidents take too long to triage, dashboards sprawl without SLOs, and every postmortem ends with "we need more logs." If nobody can name who owns error budget for checkout or the public API, you are the audience.
B2B SaaS with SLA pressure
Multi-tenant APIs where enterprise contracts reference uptime and leadership wants SLOs tied to real user journeys, not ping checks alone.
Fintech and regulated products
Payment and ledger flows need traceable incidents, audit-friendly runbooks, and paging that respects change windows.
Microservices after a split
Teams that decomposed a monolith but still debug with single-service logs and no shared trace context.
Kubernetes-heavy platforms
Clusters with Prometheus installed but alerts that page on node CPU instead of checkout latency or queue depth.
Vendor migration in flight
Moving from a legacy APM to OpenTelemetry without losing historical SLO baselines or duplicating alert noise.
Teams after a noisy on-call quarter
Alert fatigue drove engineers to mute channels. You need delivery that removes pages, not another dashboard seat.
Typical Project Scenarios
Six situations we see on discovery calls. Each maps to a bounded observability wave we can scope in the first week after the Observability Stack Readiness Gate.
Instrument checkout after microservice split
Latency regressions hide between cart, tax, and payment services. We add W3C trace propagation, span attributes for payment provider, and an SLO on successful checkout duration.
Replace CPU paging with SLO burn alerts
On-call mutes Prometheus rules that fire every deploy. We define multi-window burn rates on availability and latency SLIs and retire noisy infra thresholds.
Roll out OpenTelemetry without dual-write forever
A legacy APM agent still runs on every pod. We migrate service by service to OTel collectors with a documented cutover and dashboard parity checklist.
Link runbooks from every PagerDuty route
Pages arrive without context. We move runbooks into Git, link them from alert annotations, and rehearse one failure mode in staging.
Build executive SLO views without vanity charts
Leadership wants one screen for error budget by product line. We tie SLIs to journeys product owners already name in roadmap reviews.
Separate general observability from AI agent traces
LLM tool calls need different cardinality rules. We keep platform observability on this engagement and route agent eval work to AI agent observability development.
How Delivery Works
Six phases, usually six to ten weeks for a first observability program with instrumented critical paths, signed SLOs, tuned paging, a game day, and paired handoff documentation. Game days with documented escalation paths are non-negotiable when on-call rotation is already strained.
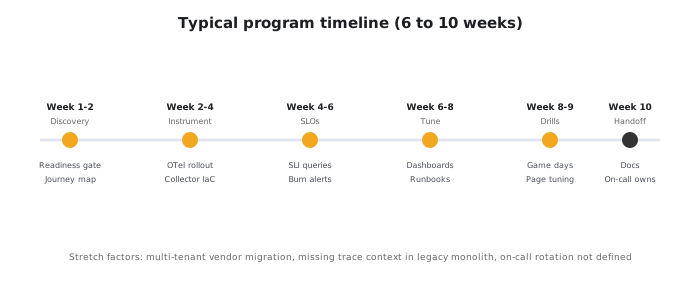
Discovery maps critical user journeys, runs the Observability Stack Readiness Gate, and documents trace gaps, SLO owners, and on-call pain. If any gate answer is undefined, we capture owners before changing alert routes.
Instrumentation delivers OpenTelemetry SDK changes, collector IaC, and sampling policies validated in staging before production traffic.
SLO design implements SLI queries, error budgets, and burn-rate alerts product owners sign in writing.
Alert and dashboard tuning retires noisy rules, links runbooks from routes, and aligns Grafana or vendor dashboards to journeys.
Drills rehearse one failure mode in staging, measure time-to-mitigate, and tune pages based on outcomes.
Handoff includes instrumentation guidelines, SLO change process, and game day checklist. Paired weeks let your on-call merge changes under our review before we step down to advisory hours or transition to project-based outsourcing for wave two.
Team Composition
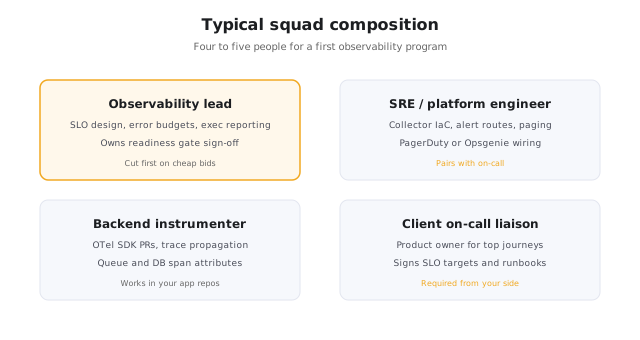
A four- to five-person squad is the usual shape for a first observability program. The observability lead who owns SLO design and readiness gate sign-off and the backend instrumenter who merges OpenTelemetry PRs are the two roles vendors cut to win on price. Those are also the roles that determine whether on-call trusts the next page.
Typical roster: observability lead, SRE or platform engineer for collectors and paging, backend engineer for trace propagation in app repos, part-time product owner from your side who signs SLO targets, and optional QA automation engineer when synthetic probes feed SLIs. For ongoing tuning after wave one, the same squad can run as an dedicated development team on a monthly retainer. For a single senior engineer inside your org, staff augmentation is the better fit.
Project, dedicated team, or staff augmentation depending on how much of the observability roadmap you want us to own.
Pricing and Engagement Models
Project-based
Fixed scope for a bounded observability program: readiness gate, OpenTelemetry rollout on critical paths, SLO and burn-rate alerts, runbook linkage, one game day, and handoff documentation. Typical duration six to ten weeks. Published bands run USD 28,000 to USD 110,000 after discovery, depending on service count, vendor migration, and regulated reporting.
Dedicated team
Ongoing squad owning SLO tuning, instrumentation backlog, alert hygiene, and game day support. USD 20,000 to USD 50,000 per month for four to six people depending on seniority mix and service surface area.
Staff augmentation
Embed one or two senior SRE engineers when you already own SLO rituals and need hands on collectors, instrumentation PRs, or burn-rate tuning. USD 6,500 to USD 12,500 per month per senior engineer on published brackets.
Compared With In-House Hiring, Freelancers, and Large Consultancies
Outsource when
- You need traces, SLOs, and runbooks in one or two quarters, not after a six-month search for a rare SRE plus backend hybrid.
- Dashboards exist but on-call still greps logs during every severity-one incident.
- Leadership wants a third party to document the Observability Stack Readiness Gate before an enterprise SLA renewal.
- OpenTelemetry migration stalled because no team owns collector IaC and app instrumentation together.
Keep it in-house when
- You already run weekly SLO reviews, error budget policy is enforced, and you only need a short spike on one service.
- Production is a single monolith with mature tracing and on-call rarely pages.
- A vendor delivers slides your engineers are not allowed to merge into repos or alert routes.
Freelancers can instrument one service quickly but rarely stay for game days or SLO governance at leadership level. Nearshore delivery from Cordoba gives you senior observability and platform profiles at a lower total cost than hiring the same mix in major US metros, with overlap platform and on-call can use. Browse case studies for examples of how we work with product teams.
Illustrative Scenario: Clearpath Freight
Composite illustrative scenario only. Not a published client case study. No performance metrics are claimed.
The situation
Clearpath Freight is a fictional B2B logistics API connecting shippers to regional carriers. Microservices replaced a monolith twelve months ago, but incidents still start with SSH and grep. Prometheus pages on node memory; customers complain about booking latency first. Product leadership wants SLOs on successful booking and label generation before renewing enterprise contracts.
They need the Observability Stack Readiness Gate passed, OpenTelemetry on booking and rating paths, burn-rate alerts product owners sign, and runbooks linked from PagerDuty before peak season load tests.
What we would deliver
An eight-week nearshore project with a five-person squad from Cordoba: observability lead, SRE, backend instrumenter, QA automation engineer for synthetic booking probes, and a product owner from the client side. Daily overlap with the US Eastern platform lead during collector rollout and game day.
- Observability Stack Readiness Gate documenting SLO owners, trace gaps, on-call signal quality, and runbook linkage signed by platform and product.
- OpenTelemetry instrumentation PRs on booking, rating, and label services with W3C propagation through the API gateway.
- SLO and multi-window burn alerts on booking success rate and p95 latency with noisy infra rules retired.
- Runbooks in Git linked from alert annotations with a rehearsed carrier timeout failure in staging.
- Handoff checklist for extending instrumentation to the remaining legacy batch jobs.
In a scenario like this, the win is predictable response: on-call opens one trace, product sees error budget impact, and leadership trusts SLO reports in QBRs.
Risks and Mitigation
Cardinality explosion after instrumentation. High-cardinality labels blow vendor bills or crash collectors. Mitigation: attribute budgets, review in PRs, and staging load tests on trace volume.
SLO targets set without product input. Engineering picks numbers leadership rejects later. Mitigation: product owner sign-off before alert routes go live.
Dual-write migration never ends. Legacy APM and OTel run forever. Mitigation: service-by-service cutover checklist with dashboard parity gates.
Alert fatigue returns after handoff. Teams add rules without retiring old ones. Mitigation: alert review ritual and runbook requirement in CI for new pages.
Trace breaks at the gateway or message bus. Mitigation: explicit propagation tests in CI and pairing with microservices development when contracts change.
Observability and platform timelines fight. Mitigation: explicit sequencing with platform engineering and DevOps engineering, with collectors treated as platform code.
Questions buyers ask before the first discovery call
Frequently Asked Questions
Staff augmentation embeds one or two SRE engineers on your backlog and rituals. Outsourced observability engineering services deliver a governed program: Observability Stack Readiness Gate, OpenTelemetry rollout, SLO and burn-rate alerts, alert and dashboard tuning, runbooks in Git, and on-call drills. You keep vendor accounts and repositories. Choose augmentation when you already run SLO reviews and need extra hands. Choose this page when incidents take hours because traces stop at the edge, alerts lack runbooks, and leadership asks for defensible SLOs.
We work with OpenTelemetry collectors and SDKs, Grafana Cloud or self-hosted Grafana, Prometheus, Loki, Tempo, Datadog, Honeycomb, New Relic, and AWS CloudWatch or X-Ray when already licensed. We align with your existing vendor contracts rather than forcing a rip-and-replace on week one. Kubernetes, ECS, and serverless workloads are in scope when trace context propagates across ingress, services, and queues.
Discovery documents the Observability Stack Readiness Gate: SLO ownership, trace coverage, on-call signal quality, and runbook linkage. Delivery includes SLI queries and error budgets, OpenTelemetry instrumentation PRs, collector IaC, burn-rate and multi-window alerts, dashboards tied to user journeys, runbooks linked from PagerDuty or Opsgenie routes, and a rehearsed game day before handoff.
Six to ten weeks is typical for a first program: two weeks on discovery and readiness gate, two to four weeks on instrumentation and collector rollout, two weeks on SLOs and alert tuning, one to two weeks on drills and handoff. Timelines stretch when a legacy monolith blocks trace propagation, on-call rotation is undefined, or product owners cannot sign SLO targets.
Project-based observability programs typically land between USD 28,000 and USD 110,000 depending on service count, vendor migration scope, and regulated reporting needs. Dedicated observability squads run USD 20,000 to USD 50,000 per month for ongoing SLO tuning, instrumentation backlog, and game day support. Senior staff augmentation for SRE engineers ranges from USD 6,500 to USD 12,500 per month per engineer on published brackets via hire SRE engineers. We confirm pricing after discovery once readiness gate answers are documented.
You do. Dashboard JSON, alert rules, collector configs, SLO definitions, and runbooks ship under your IP in your repositories and observability tenant. We document how to extend instrumentation, tune burn rates, and run the next game day without paging us. Ongoing CI/CD or platform operations stay separate engagements through DevOps engineering or platform engineering if you want managed ops after handoff.
Yes. Delivery teams are based in Cordoba, Argentina, with daily overlap on US Eastern business hours. Observability work needs same-day iteration with platform and on-call leads when a burn-rate alert fires before a release, trace propagation breaks in staging, or a game day needs a vendor engineer on the bridge.
Related Services